Observability & on-call

See it before
your customers do.

We build monitoring, alerting, and on-call practice that cuts noise and surfaces real risk — metrics, logs, traces, and SLOs wired to the journeys that matter.

  • SLO alerts
  • OpenTelemetry
  • On-call ready
Watched with
<5mMTTD targets for critical paths
SLOAlerts tied to user journeys
−60%Typical alert noise reduction
24/7Coverage models that match risk
Network operations center monitoring production signals
NOC · primary · secondary · escalation

Who it's for

Built for the people who carry the pager

  • Error budgets

    SRE / platform

    Signal standards, burn alerts, and quieter pages that still catch real pain.

    Burn-first pages
  • Journey SLIs

    Product engineering

    Traces and dashboards that explain failures without a platform ticket queue.

    Self-serve dig
  • Human-safe paging

    On-call leads

    Schedules, escalations, and runbooks people actually open at 2am.

    Runbook hit-rate
  • Evidence trails

    Security / compliance

    Retention, access, and incident timelines that survive an audit ask.

    Audit-ready

Observability

Four pillars — wired to real journeys

Select a pillar to see the signal type, metric focus, and how it connects to paging.

SLI · burn
4 golden signals

Metrics that map to users

Golden signals and journey SLIs — not vanity CPU graphs nobody pages on.

We define SLIs per journey, then burn-rate policies that page before customers tweet.

SLO board

Error budgets that page on user pain

Checkout completehealthy
SLI
99.9% success
Burn
1h: 0.4×
Login + sessionhealthy
SLI
99.95% avail
Burn
1h: 0.2×
Search results p99watch
SLI
< 400ms
Burn
6h: 1.8×
Webhook deliverypage
SLI
99.5% in 30s
Burn
1h: 3.1×

Noise control

Fewer pages. Higher trust.

before

Symptom soup

142 / week

Vanity pages train people to ignore the pager
  • CPU pages with no user impact
  • Duplicate alerts for one outage
  • No owner → ignored forever
  • Dashboards nobody trusts
after

Journey-first

~38 / week

Fewer pages — each one earns attention

  • Burn-rate on user SLIs
  • Deduped & routed by service
  • Every page has a runbook
  • Delete list for vanity noise

Capabilities

Instrument → detect → respond → improve

  1. 01
    Instrument

    Observability foundation

    Collectors, exporters, and standards so new services inherit visibility by default.

    • OpenTelemetry
    • Service catalogs
    • Env parity
  2. 02
    Detect

    SLO-based alerting

    Burn-rate alerts and multi-window policies that catch real user pain early.

    • Error budgets
    • Routing rules
    • Silence hygiene
  3. 03
    Respond

    Incident & on-call practice

    Schedules, escalations, war-room norms, and post-incident learning that sticks.

    • PagerDuty / Opsgenie
    • Severity model
    • Blameless reviews
  4. 04
    Improve

    Continuous reliability

    Game days, dependency maps, and toil reduction so ops gets healthier each quarter.
    • Chaos lite
    • Runbook tests
    • Toil backlog

On-call

Coverage that matches risk — not theater

Primary00–08 UTCPlatform EU2 pages
Primary08–16 UTCPayments US1 page
Primary16–00 UTCPlatform APAC0 pages
SecondaryAll daySRE backupstandby

Stack

Real tools we wire for signal and response

Observability toolchainSignal · route · respond
  • PrometheusMetrics
  • GrafanaDashboards
  • DatadogAPM
  • New RelicObservability
  • KubernetesWorkloads
  • DockerRuntime

Results

Quieter nights. Faster diagnosis.

Prometheus · Grafana · PagerDuty
−70% pages

From 400 noisy alerts to 12 that matter

Rewrote alerting around SLOs; on-call load dropped and MTTR improved the same month.

Challenge
On-call ignored pages because almost everything was noise.
Outcome
Journey burn alerts only; delete list cut 70% of pages in four weeks.
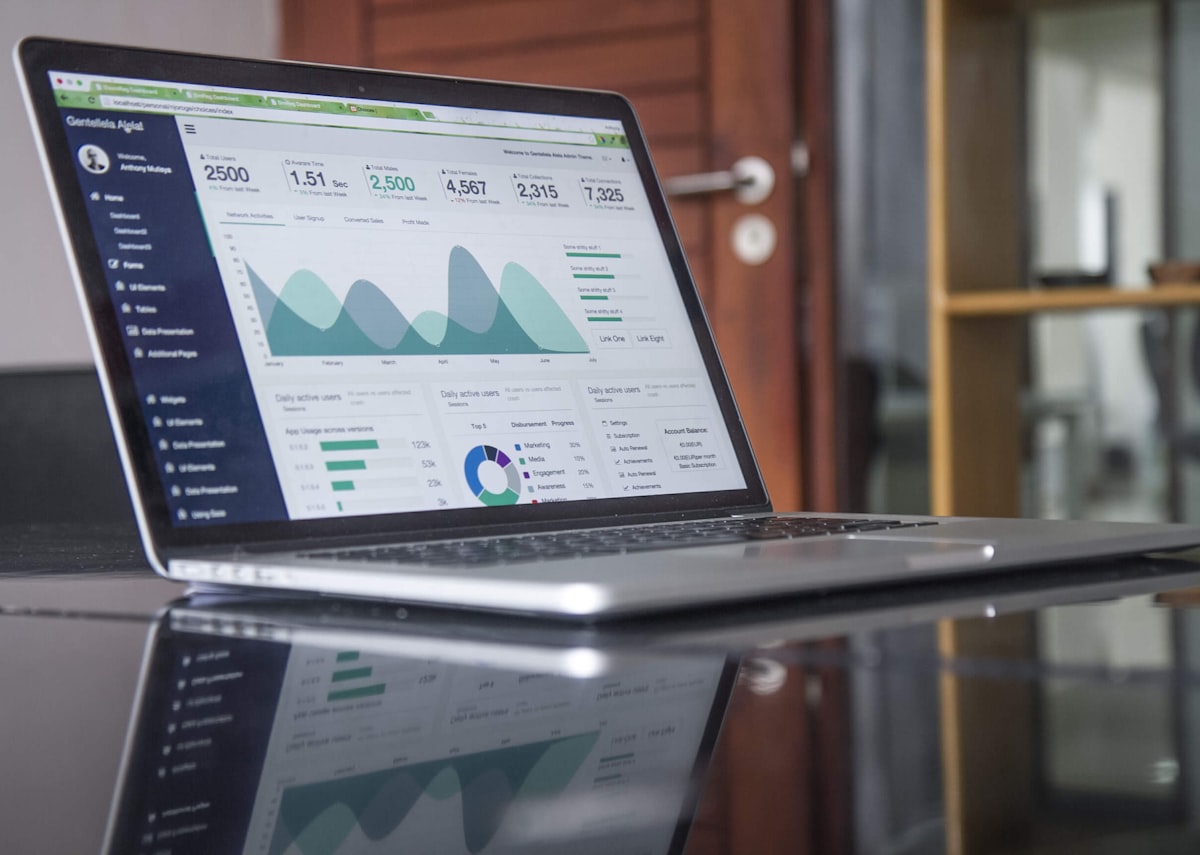
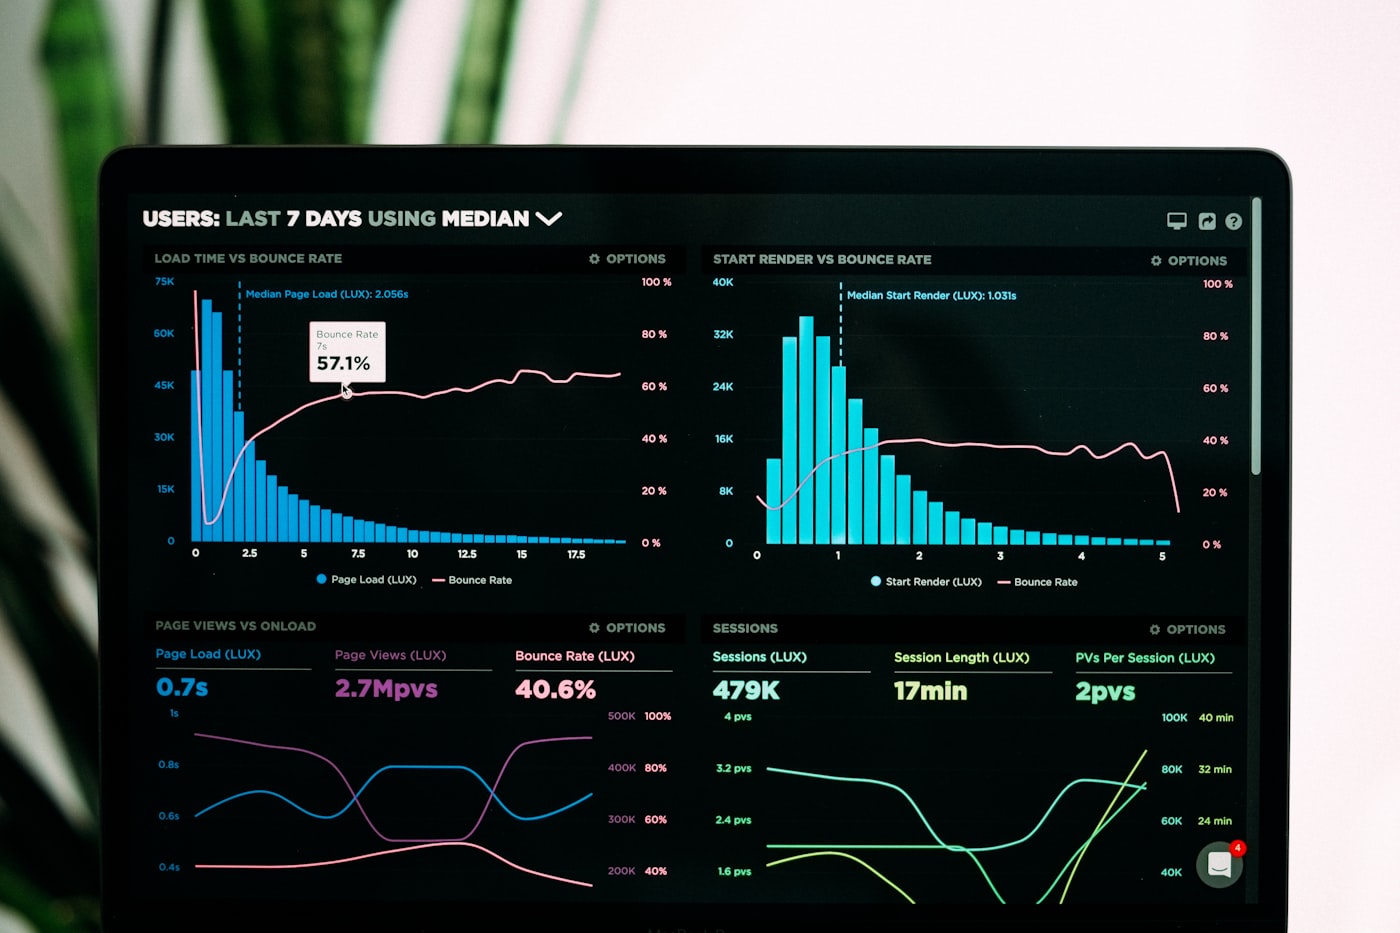
Observability dashboards and signal inventory

Deliverables

What you leave with — not just more graphs

  1. 01

    Signal inventory

    What pages today, what is ignored, what is missing.

    Audit
  2. 02

    SLO & alert pack

    Journey SLIs, burn policies, and routing by ownership.

    Policy
  3. 03

    Dashboard set

    Golden signals + critical path views operators trust.

    Views
  4. 04

    Runbooks

    First-five-minutes steps for every high-sev page.

    Playbook
  5. 05

    On-call model

    Schedules, escalations, and severity definitions.

    Roster
  6. 06

    Noise delete list

    Alerts retired with rationale — not silently muted forever.

    Cleanup

Anti-patterns

Patterns we help you retire

signal-hygiene · reject list4 findings
  • NOISE-01
    Page on every CPU blipInfrastructure vanity that trains people to ignore the pager.
  • OWN-00
    No owner on the alertPages that land in a shared void and die unread.
  • UI-DEAD
    Dashboards as decorationPretty graphs that never answer “what do I do now?”
  • SPAN-MISS
    Traces nowhere usefulSampling that skips the path that is actually slow.

Industries

Where quiet, trusted paging pays off

SaaS platforms

Multi-tenant SLOs and noisy-neighbor detection.
Fintech

Payment journey burn rates and audit-friendly timelines.
E-commerce

Checkout and search paths watched through peak seasons.

Marketplaces

Seller and buyer journeys with shared dependency maps.

Why Zupitrix

Monitoring built for humans on call

Symptom-first culture

We alert on user-visible pain, then dig into causes — not the other way around.

Ops empathy

Designs that respect sleep, attention, and the humans who carry the pager.

Stack fluency

Open source or commercial — we optimize for clarity and ownership, not license dogma.

  1. 01Signal audit

    What exists, what pages, what is ignored.

    1–2 wks
  2. 02SLO design

    User journeys, budgets, and alert policies.

    1–3 wks
  3. 03Implement

    Dashboards, collectors, routing, and runbooks.

    2–6 wks
  4. 04Drill & operate

    Game days, tune noise, optional managed watch.

    Ongoing

FAQ

Questions about 24/7 monitoring

Tired of pages that mean nothing — or silence that means trouble?

Tell us what broke last quarter — we will propose an observability and on-call plan that fits.

Start Project
Contact Us

Get In Touch

Let's build something amazing together. Contact us to discuss your project and see how we can help bring your vision to life.

New project inquiry

Start project.
We'd love to help.

Fill in the form and we'll respond within one business day — personally, not with a template.

Your info stays private